
Inference
Run inference anywhere. Improve continuously.
Run production inference on Oumi-managed GPUs, in your private VPC, or on-premises. Choose the infrastructure that fits your workload, monitor serving health and model quality, and continuously feed production signals back into the next improvement cycle.
INFERENCE
Deploy models on the infrastructure that fits your workload.
Serve trained or imported models behind production inference endpoints, with control over serving hardware and where your models run.
Managed inference
Deploy models to Oumi-managed GPU infrastructure and call them through familiar APIs. GPUs scale with your traffic: zero when it stops, hundreds when it surges.
GPU selection
Choose the serving hardware that fits your latency, throughput, and cost requirements, including A100 80GB, H100 80GB, H200 141GB, and B200 180GB.
Private inference
Serve models inside your private VPC, on-premises environment or edge when inference needs to remain within infrastructure you control.
Model export
Export trained model artifacts and serve them independently on your own infrastructure.
MONITORING
Monitor inference health. Measure model quality.
Track inference latency, throughput, errors, and model quality in one place. Detect regressions, analyze failures, and turn production insights automatically into targeted improvements.
Service health
Monitor request volume, error rate, P50/P95/P99 latency, time to first token, and token throughput.
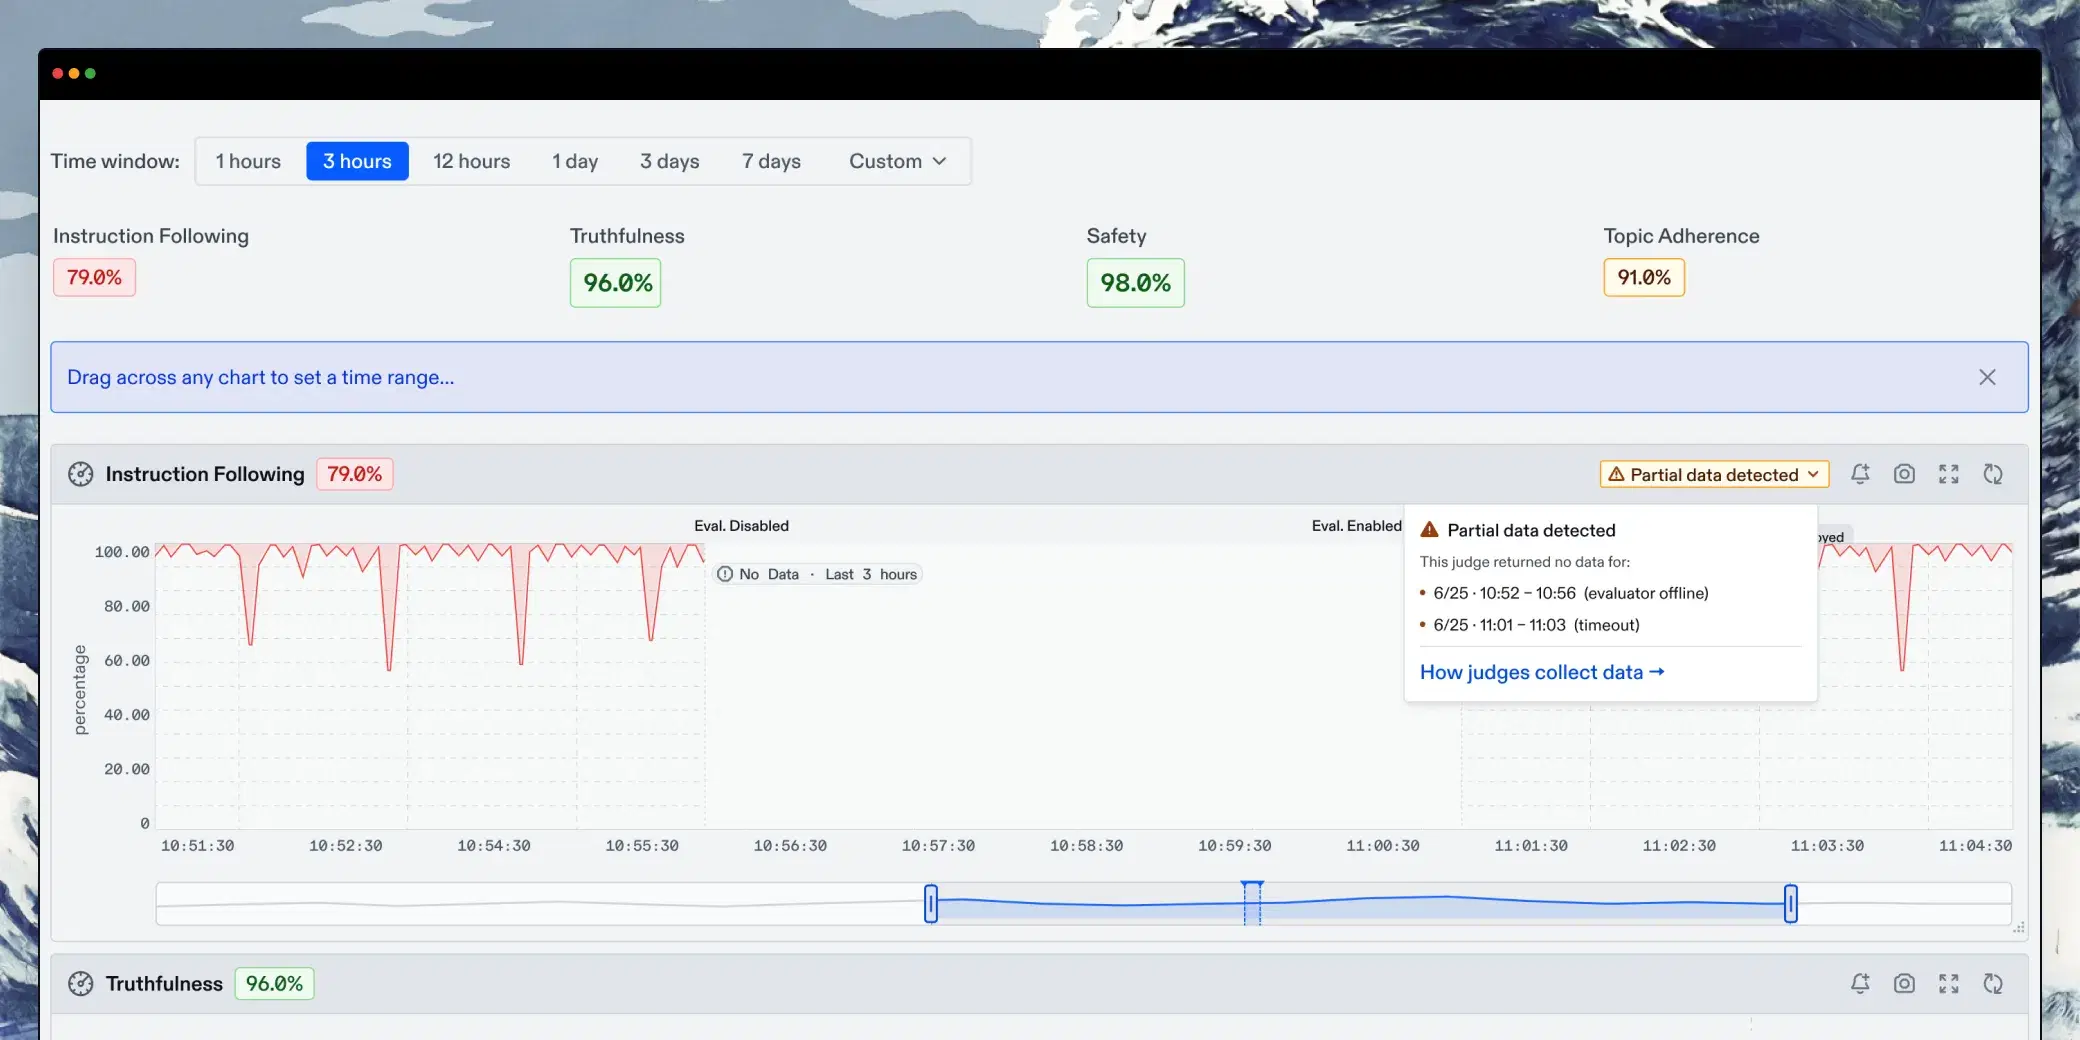
Production evaluations
Run evaluators against sampled production traffic and track quality scores over time. Use the same evaluators from training and monitor them in production.
Failure modes
Analyze poorly performing production traffic to identify new systematic failures.
Inference logs
Inspect individual production requests and turn useful traffic into datasets for future evaluation or training.
CONTINUOUS MODEL IMPROVEMENT
Turn production signals into the next model improvement.
Use production evaluations and failure modes to identify where models are underperforming, create targeted datasets from real production examples, and feed those datasets back into training.
Build AI your business owns.
Start with the task. Oumi connects the work, your team controls the decisions, and the intelligence runs where your business needs it.